VGI-Bench: Probing Visual Intelligence in Video Generation Models
v3
Paper introduction · English narration and external captions
v3
Paper: VGI-Bench: Probing Visual Intelligence in Video Generation Models (v3) https://arxiv.org/html/2608.19583v3
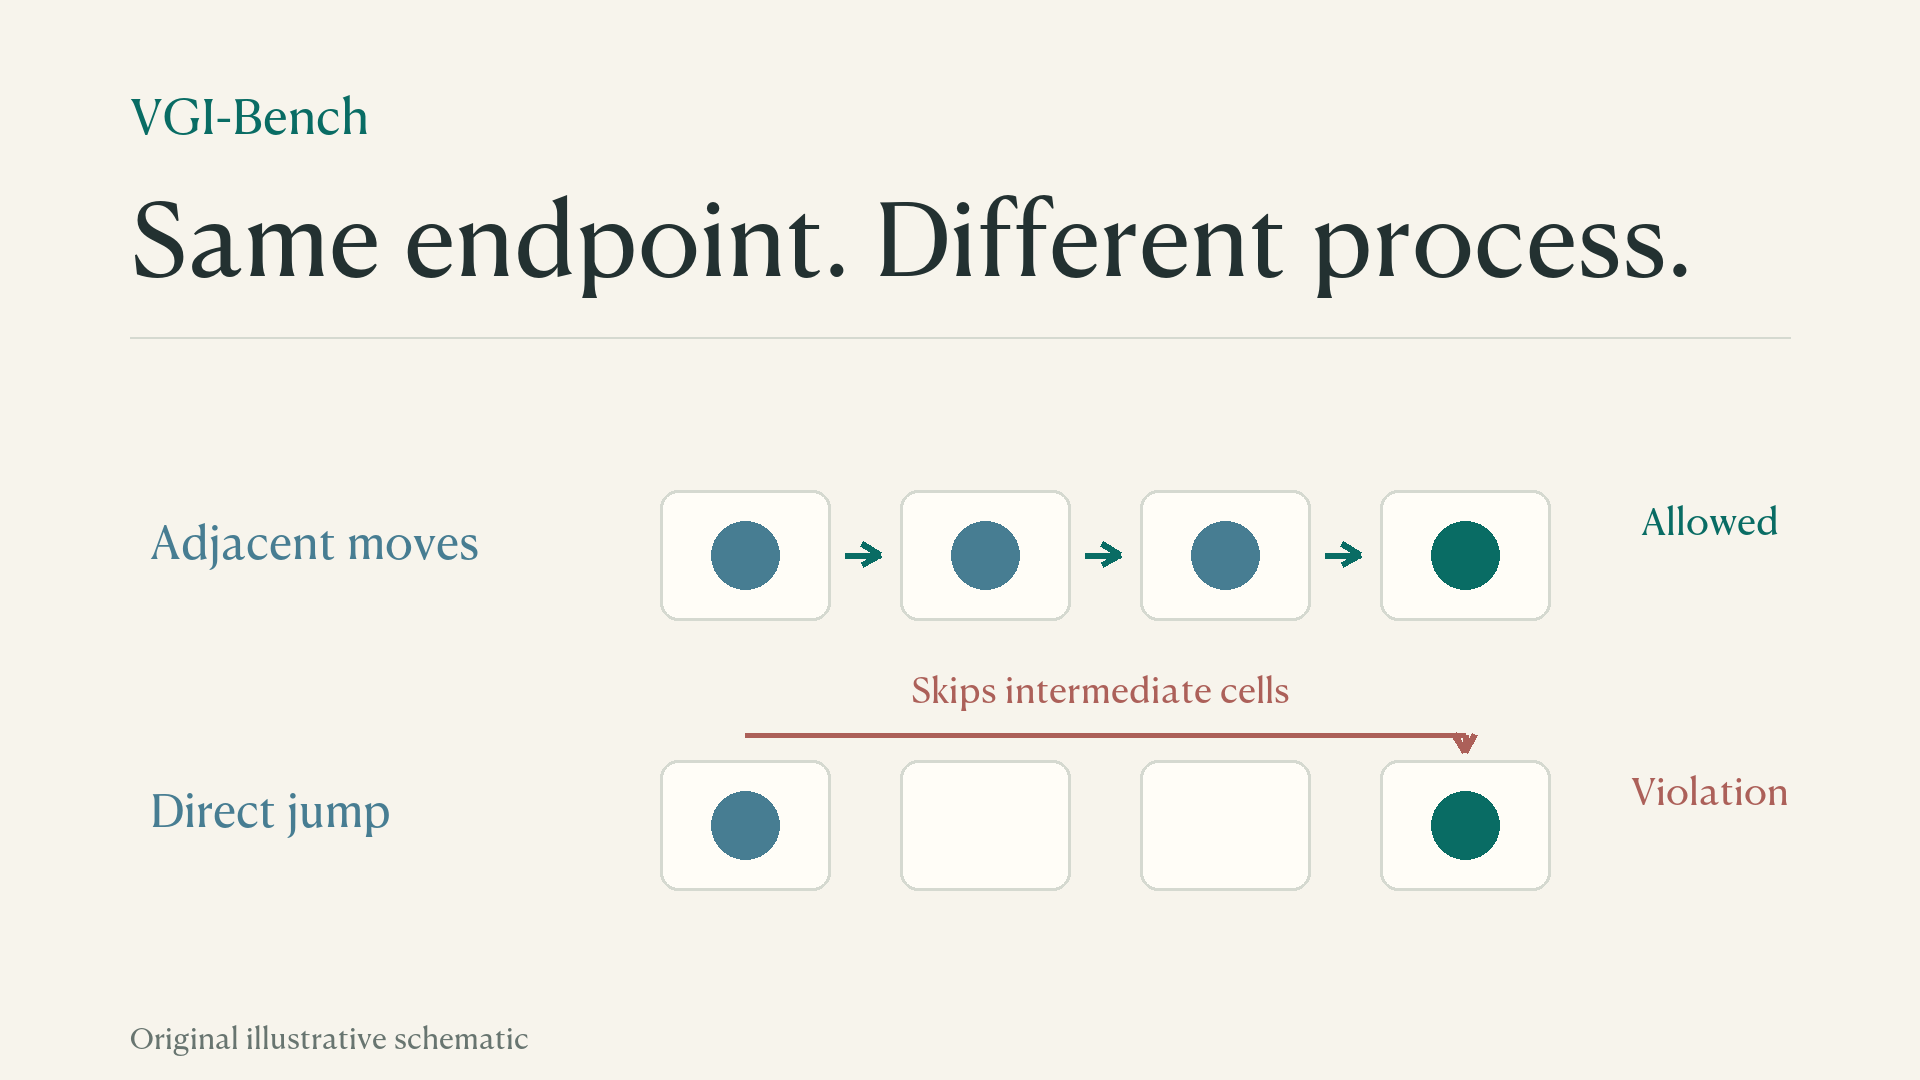
A picture can show where an object ended up while hiding how it arrived. VGI-Bench makes intermediate rule preservation part of visual-intelligence evaluation.
VGI-Bench studies reasoning expressed through generated video. Each task supplies an initial image and instructions defining the goal, relevant objects, allowed actions and shortcuts to avoid. The suite contains 27 task types in four mutually exclusive domains, with seven nonexclusive skill tags. A task belongs to one domain but can require several skills.
Evaluation separates progress from adherence. Task-specific complete, partial and failed tiers map to 1, 0.5 and 0. Local rubric items count violations and average their scores. The final composite multiplies completeness by rubric adherence. A motionless clip can avoid violations without progressing; an illegal jump can achieve an endpoint without following the procedure. Strict success separately requires perfect completion and adherence.
The main evaluation uses half of each task’s instances with a fixed random seed and a Gemini3 Flash evaluator. Reported overall scores include 51.0 for Seedance2.0, 44.0 for Kling3.0 and 36.7 for Sora2. These are composite benchmark results under published generation configurations, not universal correctness percentages.
A separate analysis examines decoded intermediate states during denoising. Wrong-to-correct transitions remain at or below 0.9% per sampled checkpoint pair in that experiment. Denoising order is not the timeline of events inside the finished video. The useful distinction is to keep the goal, allowed route and measurement procedure visible, rather than accepting visual polish as evidence of valid reasoning.
Watch the companion English animation with external English, Simplified Chinese or bilingual captions.
Paper, exact arXiv v3: https://arxiv.org/html/2608.19583v3
#VideoGeneration #VisualReasoning #AIResearch
Clean English video. Choose English, Simplified Chinese or bilingual captions in the player.