xDailyBench: Benchmarking LLMs on Professional Consultation for Real-Life Problems
v1
Paper introduction · English narration and external captions
v1
Paper: xDailyBench: Benchmarking LLMs on Professional Consultation for Real-Life Problems (v1) https://arxiv.org/html/2609.07784v1
A requirement can be unstated in the opening request and still be fully available in the supplied background. xDailyBench turns that difference into explicit evaluation criteria.
xDailyBench assembles professional-consultation tasks from requests people used AI for or intended to complete. Each task supplies an instruction, optional workspace materials and relevant context. Some requirements are stated directly. Others are basic expectations, such as accuracy and usable formatting. Still others follow from the particular background provided to the agent. The benchmark asks whether those pieces are connected, rather than whether the assistant invents information it never received.
The final collection contains 248 tasks across 51 scenarios. Task-specific rubrics describe requirements instead of one unique reference answer. Each criterion receives a binary judgment, with weights expressing its importance to the task. A weighted score can recognize useful partial progress while preserving unmet conditions. It must not be read as the share of tasks completed perfectly.
The quality process combines assisted screening, cross-review and a pilot comparison of automatic and human criterion judgments. The main evaluation covers eleven models with matched instructions, tools and budgets. Two models tie at a reported task-level score of 75.6%; that average is separate from pooled criterion comparisons.
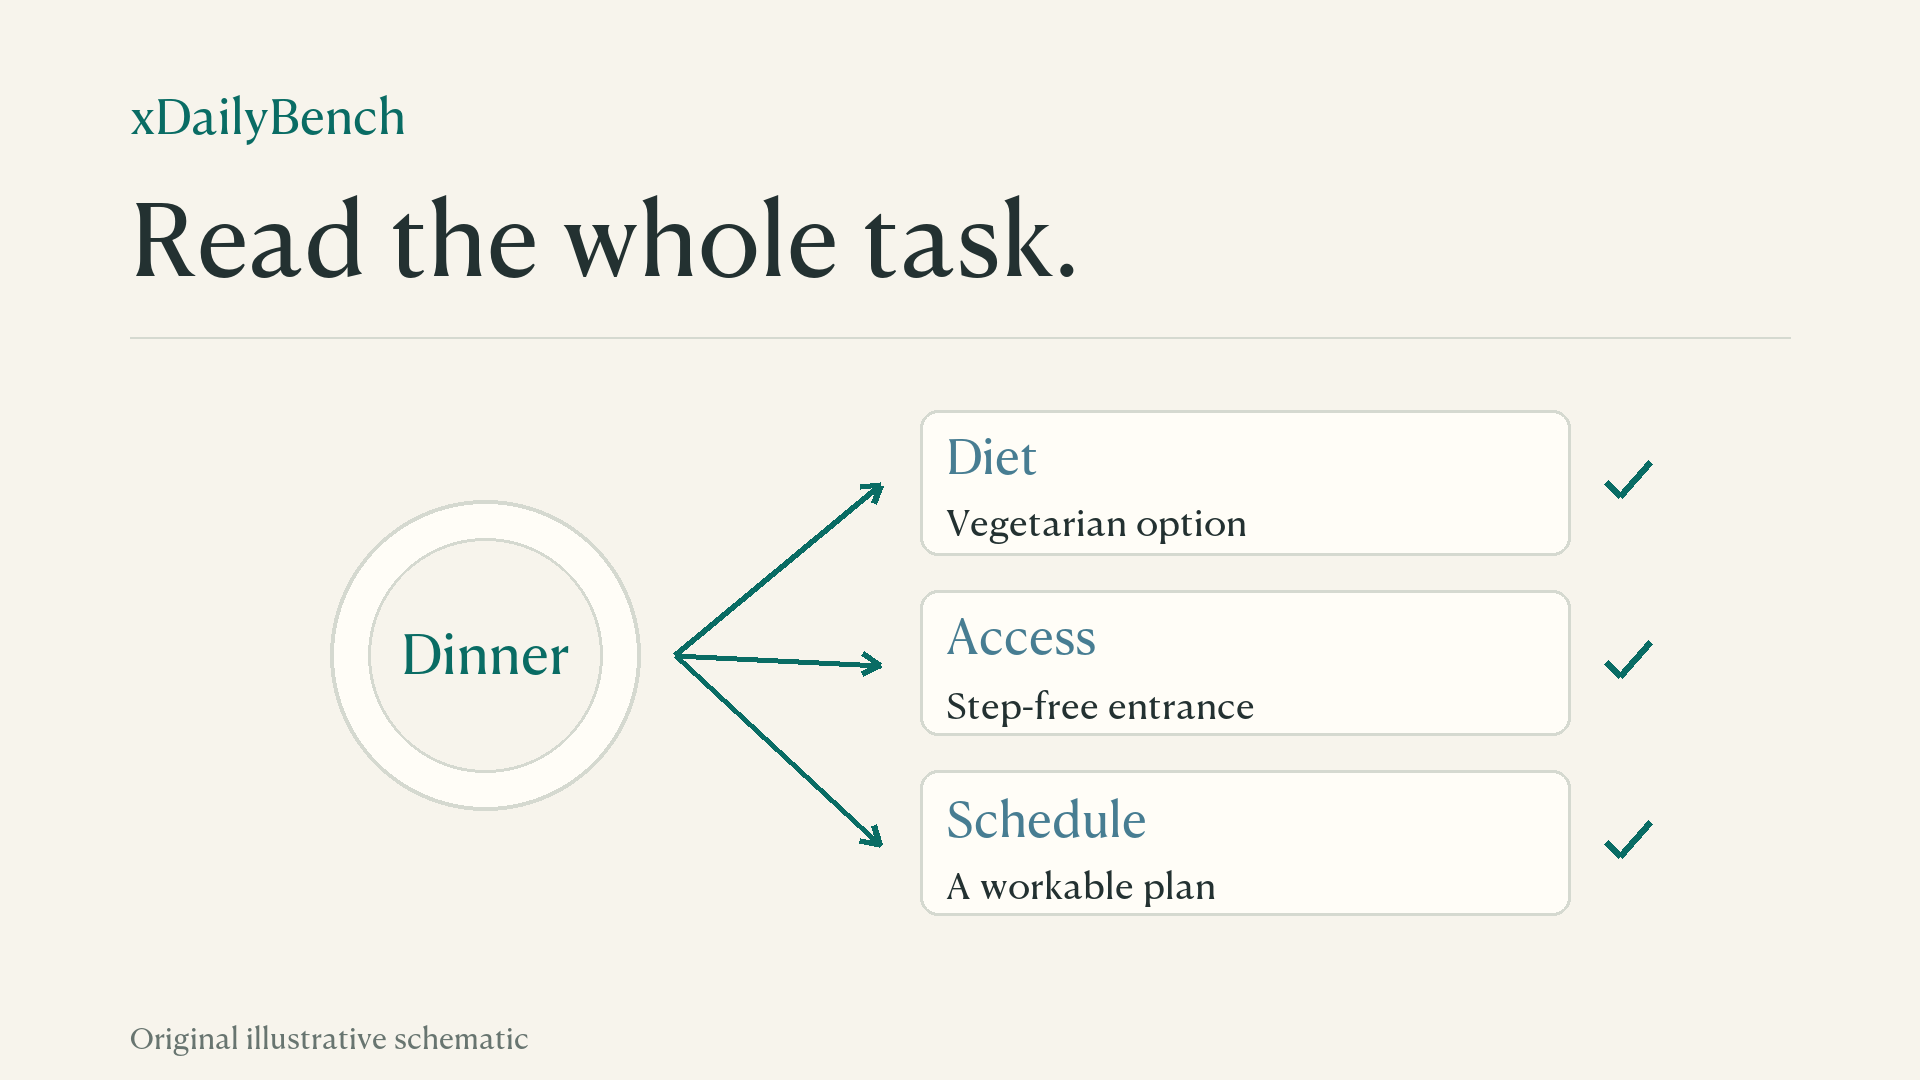
For Seed-2.1-Evolving, explicit criteria score 81.0% and implicit criteria 65.0%, a 16-percentage-point gap. The useful lesson is to examine what the response failed to connect. In our dinner illustration, access and dietary requirements belong to the task even when they are not repeated in its first sentence.
Watch the companion English animation with external English, Simplified Chinese or bilingual captions.
Paper, exact arXiv v1: https://arxiv.org/html/2609.07784v1
#LLMEvaluation #AIResearch #AIAgents
Clean English video. Choose English, Simplified Chinese or bilingual captions in the player.