OpenSkill: Open-World Self-Evolution for LLM Agents
v1
Paper introduction · English narration and external captions
v1
Paper: OpenSkill: Open-World Self-Evolution for LLM Agents (v1) https://arxiv.org/html/2606.06741v1
OpenSkill evolves explicit external agent skills rather than model weights. Its loop connects open-world retrieval, structured skill planning, virtual verification and final deployment under hidden target tests.
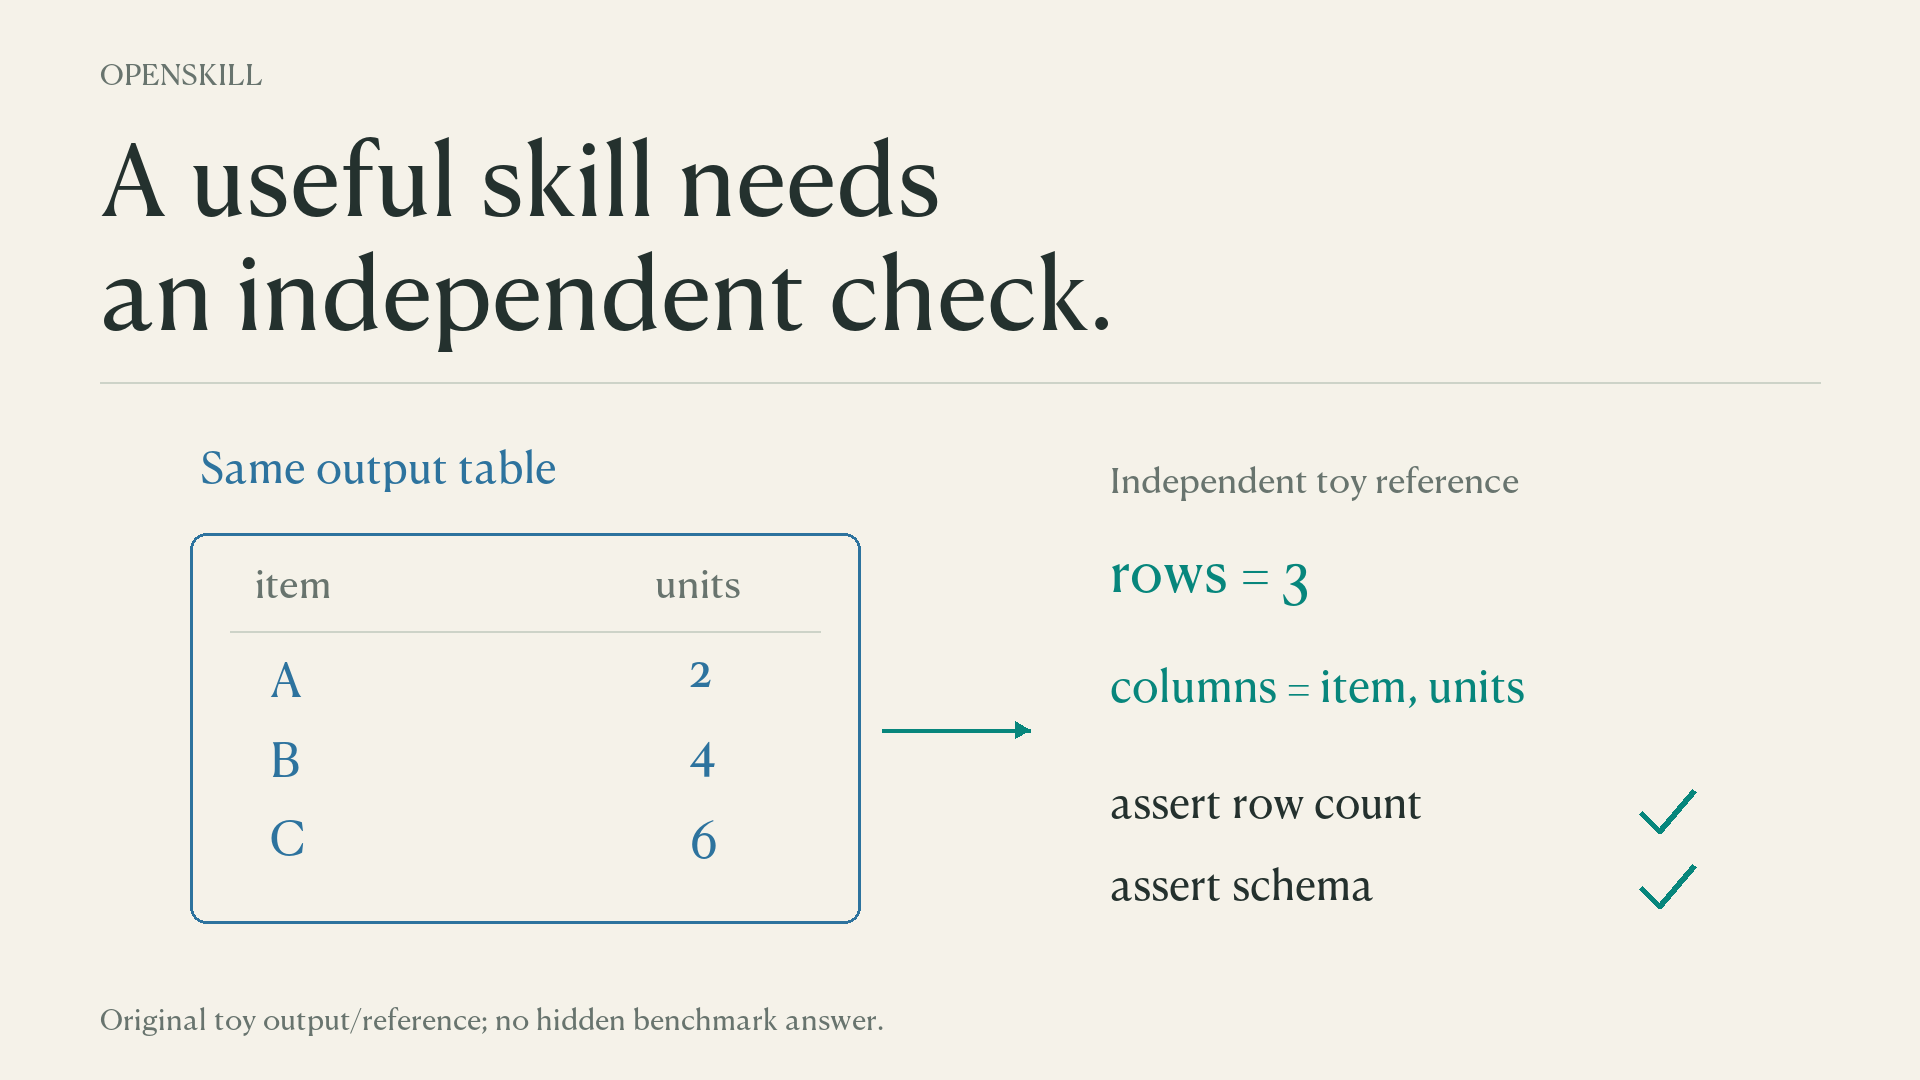
Retrieved procedural knowledge describes how to carry out a task. Verification knowledge supplies independently checkable reference values, invariants, procedures and expected formats. A toy dataset example in the film keeps those roles visible: the loading procedure produces a table, while a known row count of three and item/units schema become assertions against that output.
A plan specifies architecture, key procedures and domain rules for one to four skills. They are refined jointly in one session. An isolated verifier constructs deterministic checks; executing the skills provides per-assertion failures, diagnosis and revision suggestions. A knowledge-gap classification can trigger additional targeted retrieval.
The default loop allows three refinement rounds, with pass, stall and budget stopping controls. The final refined skill set is frozen for zero-shot deployment rather than regenerated for each target evaluation. Retrieval queries filter benchmark names and identifiers that could lead toward hidden test materials.
The source nevertheless does not support an absolute no-ground-truth-signal slogan. Appendix F mentions one ground-truth-derived pass/fail bit when the verifier is asked for deeper surrogate tests. Test contents, assertions and expected values remain hidden.
Reported SkillsBench pass rates are 25.5% before and 43.6% with OpenSkill for the Opus4.6 target agent, and 25.0% versus 42.1% for GPT-5.2. Virtual-verifier agreement is separately 60.7% on 84 tasks. These figures measure different parts of the pipeline. The companion film explains how an independently grounded proxy is constructed and why its agreement with the target outcome still needs to be measured.
Pinned source versions: Paper, v1: https://arxiv.org/html/2606.06741v1
#AIAgents #AgentSkills #AIResearch
Clean English video. Choose English, Simplified Chinese or bilingual captions in the player.