Function-Aware Fill-in-the-Middle as Mid-Training for Coding Agent Foundation Models
v3
Paper introduction · English narration and external captions
v3
Paper: Function-Aware Fill-in-the-Middle as Mid-Training for Coding Agent Foundation Models (v3) https://arxiv.org/abs/2607.12463v3
Function-aware FIM adds a dedicated preparation task before agentic post-training: reconstruct complete implementations from their visible relationships within a file. The reported results concern the finished coding-agent pipeline after that sequence.
The selector first builds a program dependency graph. It identifies function nodes, caller-callee edges and sibling links for methods in the same class. It can select one function or connected pairs and triples, keeping signatures and external context while masking bodies. Target docstrings are masked as well, preventing them from simply exposing the desired implementation.
Selection scores combine complexity and inferability. Substantial code logic is useful only when visible arguments, helpers, signatures and related methods provide sufficient clues. Joint masking recomputes that contextual support because a hidden helper can remove a clue available in a single-function example.
A Gemini-3-Flash teacher sees the masked file and generates a rationale followed by a candidate body. It does not see the original hidden implementation. A separate judge can compare the candidate with the original code for correctness, executability and API use. Retained examples become supervised masked-file-to-response pairs.
The selected corpus contains approximately 2.6 billion tokens from 968 Python repositories under the Qwen2.5-Coder tokenizer. In one matched 14B R2E-Gym result, the reproduced post-training-only baseline solves 26.20% of SWE-Bench-Verified instances, while adding FIM mid-training reaches 29.20%. These are means over three evaluation runs.
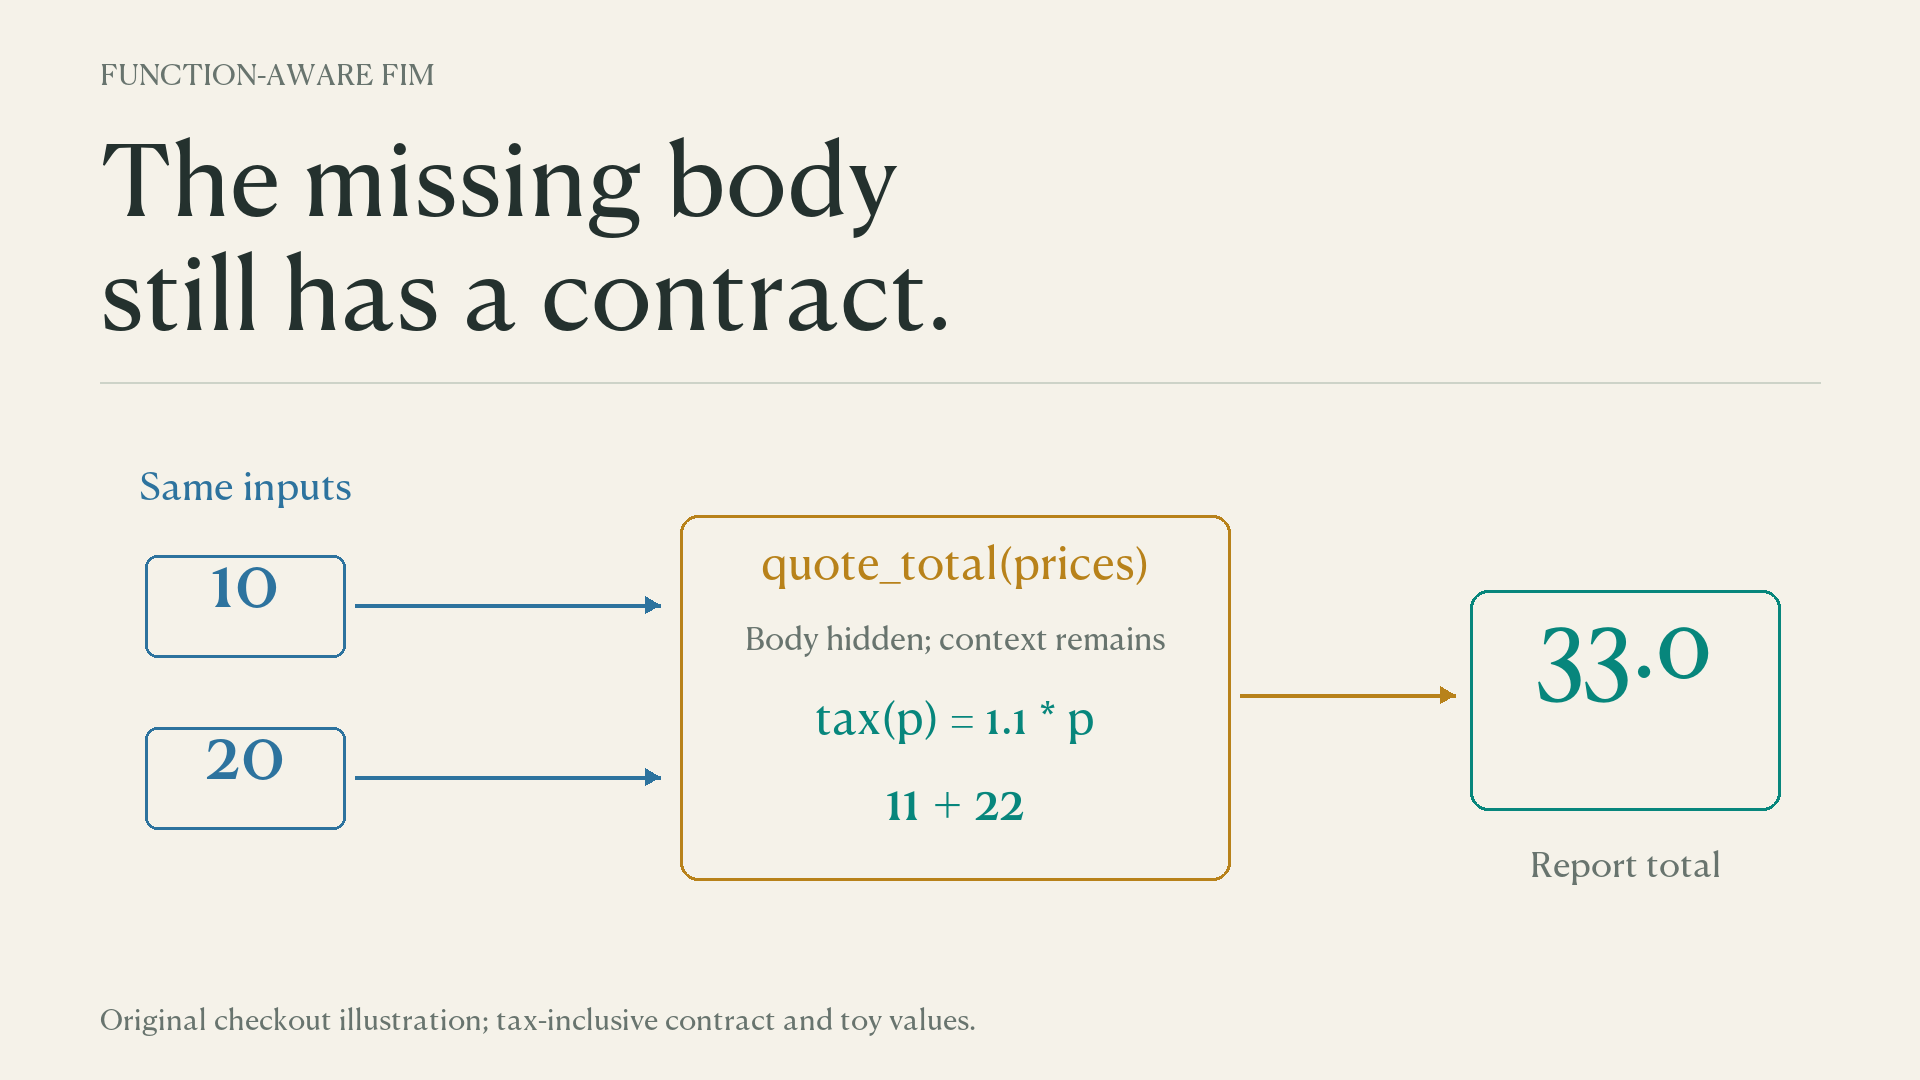
A separate 7B selection ablation holds a 200,000-target budget and teacher rationale augmentation fixed. Random selection averages 13.91% across Verified and Lite; the full selector averages 15.61%. The companion film uses an original checkout example to explain these dependencies. Evidence follows the supplied 27-page draft; the declared public reference is arXiv v3, whose external equivalence remains under source-link review.
#CodeModels #AIAgents #MachineLearning
Clean English video. Choose English, Simplified Chinese or bilingual captions in the player.